Proof: what we ran
One real run of readnode on mainnet: an AWS server provisioned by
readnode provision, a Snapchain read node synced from a snapshot, and the
readnode client posting, following, liking and filtering through that node.
All times are IST. Every hash below is a real mainnet message, and you can check each one against any Snapchain node (how).
Summary
| Server | AWS m5.xlarge (4 vCPU, 16 GB), 2 TB gp3, Ubuntu, ap-south-1 (Mumbai) |
| Snapchain | v0.14.3, read node |
| Provisioned | 2026-10-22 10:46 |
| Fully synced | 2026-10-23 06:04 (19 h 18 m) |
| Database | 557 GB, 914,307,183 messages, 3,356,371 FIDs |
| Test account | FID 3356482, registered onchain for this test |
| End-to-end client test | passed (06:05, rerun 08:35) |
| Cost | about $0.46/hour, so about $9 until synced (estimate) |
Timeline
| Time | What happened |
|---|---|
| Oct 22 10:46 | readnode provision --provider aws launches the instance |
| 10:47 | cloud-init done (READNODE_PROVISION_COMPLETE); Snapchain starts downloading the snapshot |
| 11:51 | Swapped in readnode-snapshot, readnode's own downloader, mid-run (see problems). provision now installs it from the start |
| 14:52 | Snapshot downloaded and unpacked: 557 GB. Snapchain starts and begins catching up |
| Oct 23 02:56 | First client test: the app key was accepted, but the node was still behind and didn't list it yet. Test timed out |
| 06:04 | Every shard within 30 s of the network head. Client test reruns |
| 06:04 | Seed, app key, cast and follow pass. Like fails: 400 invalid reaction type |
| 06:06 | Fixed (0cfad07), client rebuilt, test reruns: all checks passed |
| 08:35 | Test rerun: all checks passed again |
| Phase | Took |
|---|---|
| Provision (instance, Docker, Snapchain config) | about 1.5 min |
| Snapshot download and unpack | 4 h 05 m |
| Catch-up to the network head | 15 h 12 m |
| Total | 19 h 18 m |
Catch-up was the slow part. Mumbai is far from most Snapchain peers, which sit
in us-east-1, so the tutorial now recommends us-east-1.
The end-to-end test
packages/readnode/scripts/smoke-test.mjs drives the same HTTP API the client
UI uses. It doesn't trust a write's 200: it reads each one back from the node.
Output from the 08:35 rerun:
node http://52.66.85.241:3381, fid 3356482, custody 0xcD57f16cDF62Fb051924e0E6E7314D5DDa703A12
  ok  seed imported, custody matches, 100 cast slots
  ok  app key 0x33a5fad5… registered (requestFid 3356482) (0 s)
  ok  cast 0xc46b7911… on the node (6 s)
  ok  follow of fid 1356870 on the node (0 s)
  ok  like of 0x4ac7ab4c… on the node (0 s)
  ok  feed has 25 casts from 3 clients; ours is fid:3356482
  ok  include fid:3356482: 5 casts; exclude it: 20 casts

All checks passed.
The follow and the like show 0 s because they already existed from the
06:05 run. Writing them again is a no-op, and the test still confirms them on
the node. The log counts 3 clients because it ran before the client-labeling
fix below: two Farcaster-app keys counted as separate clients. They now count
as one, @warpcast.
Posted to mainnet
Everything here went out through the readnode client and the node above, from test FID 3356482.
App key. A gasless KEY_ADD: no Optimism transaction and no gas.
| Key | 0x33a5fad5f268fa97e020c1e996fe71f78149cd047d107731dcb3788c1b4aa43e |
requestFid |
3356482 (the client identifies itself as this FID) |
| Lifetime | 30-day TTL, sliding |
Casts
| Hash | What |
|---|---|
0x49cf4c80560ff05f6f89502f81ba62d90e9f5e49 |
"Hello from readnode…" (first test, 06:04) |
0x043c53550a2f9413204f0cac2eb7a6ce039e3b22 |
"Hello from readnode…" (after the fix, 06:05) |
0xe89cce326e9ceaed7cd01bd321e13cd3c87388fd |
"Posted from readnode…" |
0x92ca540a0f28bc32f857922fe679332d70da7152 |
the same text, as a reply to the readnode announcement |
0xc46b79118d2320ebba845d255216951a30af314d |
"Hello from readnode…" (08:35 rerun) |
Follows: FID 1356870 (vaibhavmule) and FID 37 (balajis.eth).
Likes
| Reaction hash | Target |
|---|---|
0x6d9d293c761a0cccba7c43c56043d6489b0fc765 |
Balaji's bounty post |
0xa9f5a7d8cc2d80f2cb5058a787432f4fb553785d |
the readnode announcement |
0x379c6a733853a5958acc0f90b67e0c33db719866 |
a cast by FID 1356870 |
The client on the synced node
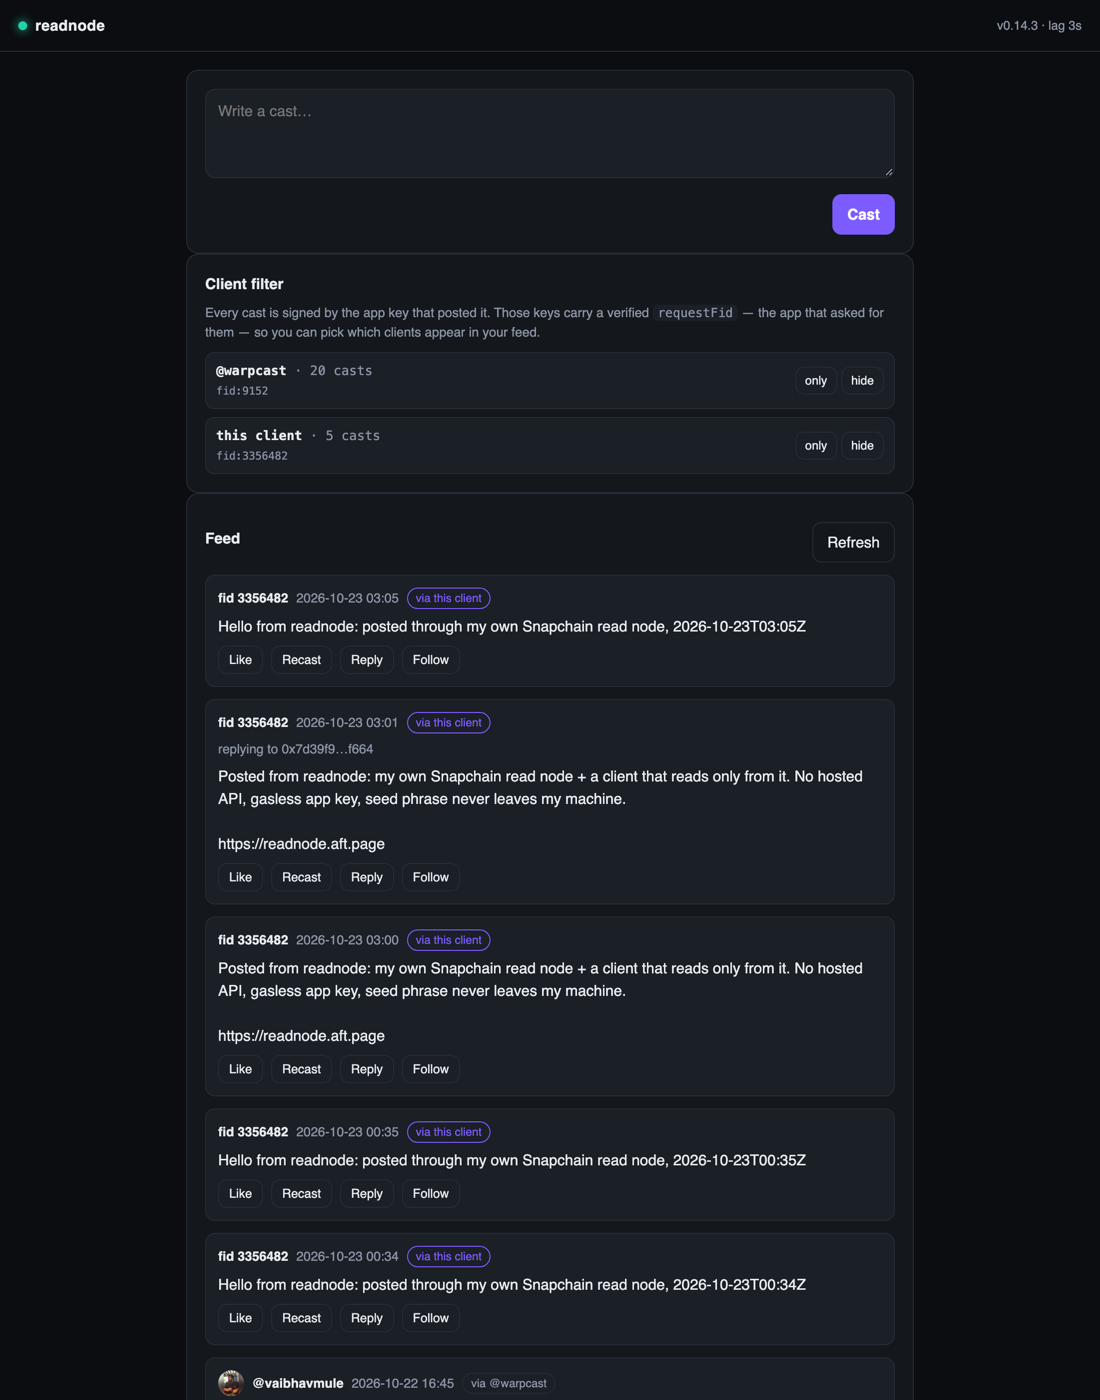
The filter lists the apps that signed the casts in your feed: @warpcast
(FID 9152, the Farcaster app) and this client. only shows just that app's
casts and hide removes them. The label comes from the requestFid signed
into each app key.
The node once synced
blockDelay |
4 s on each of shards 0, 1 and 2 |
| Database | 557 GB (approxSize 558,400,971,957 bytes) |
| Messages | 914,307,183 |
| Disk | 564 GB used of 2 TB |
| Memory | 1 GB used, 10 GB page cache, of 15 GB |
| Load | 0.08 (1-minute average) |
| Read from India | castsByFid in 48 ms |
Problems we hit
Running on real infrastructure surfaced these. Each is fixed in the repo.
| Problem | Fix |
|---|---|
| The cloud install path had never run for real and failed on first boot | 2fafd68 |
| Snapchain's built-in downloader can wipe a half-downloaded shard when the daily snapshot rotates | readnode-snapshot fetches the snapshot itself and keeps finished chunks (6c8b839), downloads the next shard while the last one unpacks (bda9de8) |
The snapshot host (r2.dev) returned 429s, 500s and dropped connections |
more, slower retries (ca416da); stalled chunks are dropped and retried (e29f2e7) |
| The app key is stored on shard 0, but a lagging node checks casts against the FID's own shard, so it rejects posts | the test waits for sync, and the tutorial explains it (99e3e11) |
Like and recast always failed with 400 invalid reaction type |
send the ReactionType enum, not its name (0cfad07) |
| Keys added onchain (every key from the Farcaster app) showed as raw keys in the client filter, not as apps | decode the requestFid from the key's onchain SignedKeyRequest metadata |
What ran live and what didn't
readnode provision --provider aws |
ran live (this run) |
| Snapchain read node from snapshot to synced | ran live |
readnode client: seed import, gasless app key, cast, reply, follow, like, feed, include and exclude |
ran live |
Onchain test-account registration (register-test-account.mjs) |
ran live; FID 3356482 |
readnode-snapshot |
ran live, but swapped in by hand partway through the run. provision now installs it at boot; that path has not had a full fresh run yet |
--provider gcp, hetzner, ssh |
dry-run only |
| Recast from the UI | same code path as like, not separately run on mainnet |
Cost
These are estimates from AWS list prices for ap-south-1. The invoice is not
in yet.
m5.xlarge |
about $0.20/hour |
| 2 TB gp3 | about $0.26/hour |
| Until synced (19 h 18 m) | about $9 |
| Per day left running | about $11 |
Delete the instance and its volume when you're done. A read node doesn't need to stay up for anything else.
Check it yourself
Any Snapchain node will return these messages, including the one you run:
NODE=http://YOUR_NODE:3381
curl "$NODE/v1/castById?fid=3356482&hash=0x043c53550a2f9413204f0cac2eb7a6ce039e3b22"
curl "$NODE/v1/castsByFid?fid=3356482"
curl "$NODE/v1/reactionsByFid?fid=3356482&reaction_type=Like"
curl "$NODE/v1/signersByFid?fid=3356482"
To reproduce the whole run, follow the tutorial on a test account and run the end-to-end test against your own node:
readnode client &
node packages/readnode/scripts/smoke-test.mjs --follow <any fid>
Vouches
None yet. If you run readnode end to end, post what happened on Farcaster: how long it took, what it cost, and what broke. Reply to the announcement and we'll link it here.